


Chinese artificial intelligence (AI) companies, including MoonShot AI and DeepSeek, are rapidly closing the technological gap with US big tech firms.
MoonShot AI's latest model ranked 4th in a global AI comprehensive performance evaluation, reducing the gap with the top US model to just 3 points. DeepSeek secured 1st place among publicly released models, ranking 2nd overall in a cybersecurity AI performance evaluation.
According to the latest announcement on the 26th by global AI model analysis and evaluation firm Artificial Analysis (AA), MoonShot AI's 'Kimi K3.1 Pro' scored 55 points on AA's comprehensive performance metric, the 'Intelligence Index (II),' placing 4th overall. DeepSeek's 'V4.1 Flash 1017' achieved a 57% task success rate in AA's Cyber Index evaluation, ranking 2nd overall.
Chinese AI models are now challenging US-leading models not only in general-purpose generative AI but also in specialized domains.
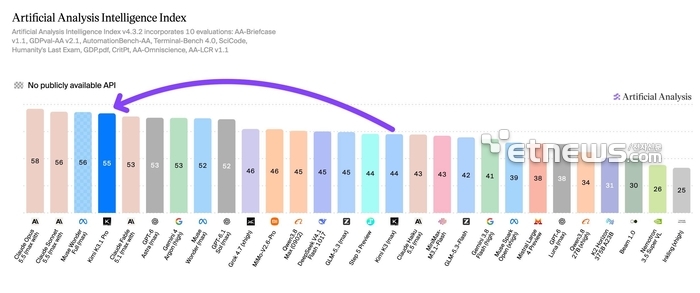
MoonShot AI's Kimi latest model trails only 3 points behind Anthropic's 'Claude Opus 5.5' (58 points), which ranked 1st. It is just 1 point behind the joint 2nd place holders: Anthropic's 'Claude Sonnet 5.5' and Meta's 'Muse Wonder Full' (each 56 points).
It also outperformed OpenAI's 'GPT-6 Astra' (53 points) and Google's latest model 'Gemini 4 Agon' (53 points), both evaluated as general AI (AGI). The significant 11-point improvement from its predecessor 'Kimi K3' (44 points) is credited for its sharp performance enhancement.
In 'GDPval-AA', which evaluates AI agents' real-world task execution capabilities, it scored 1,846 points, ranking 3rd overall. On 'TerminalBench 4.0', assessing AI agent task performance in terminal environments, it achieved 67%, securing 1st place. It also recorded 73% on 'AutomationBench-AA', which evaluates enterprise automation capabilities.
AA predicts that once the Kimi K3.1 Pro model weights are released, it will become the top-performing open-weight model.
DeepSeek stood out in cybersecurity-specialized models. In AA's 'Cyber Index' evaluation, DeepSeek's 'V4.1 Flash 1017' achieved a 57% task success rate, ranking 2nd overall. The 1st place was OpenAI's 'GPT-6 Sol Daybreak Blue' with 69%.
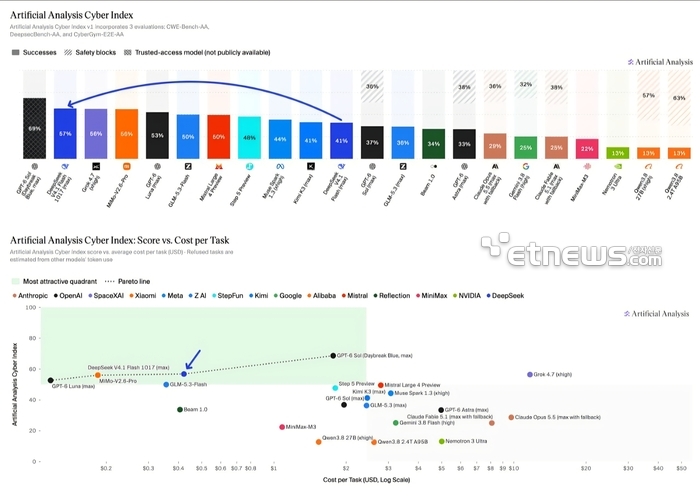
DeepSeek's new model achieved the highest score among fully disclosed specialized models. OpenAI provides its Daybreak model exclusively to national agencies and enterprises with access rights. It also leads in cost competitiveness. For cybersecurity evaluation tasks, DeepSeek's model averages $0.42 per task, just 23.33% of GPT-6 Sol's $1.80 cost.
In the 'CyberZim-E2E-AA' evaluation, which assesses the ability to detect and fix vulnerabilities in real software (SW) environments, DeepSeek's model garnered attention with a 76% task success rate. As AI-driven SW vulnerability detection, such as recent PHP flaw identification, gains traction, its role is expected to grow significantly.
An industry insider emphasized, “Chinese AI companies are simultaneously targeting top performance and cost efficiency, so Korea must accelerate its technological development.” They added, “As both the U.S. and Chinese governments push to ban exports of cutting-edge AI models, South Korea must secure competitive frontier AI models based on domestic technological foundations.”